MOTOSHARE 🚗🏍️
Rent Bikes & Cars Directly from Owners
Motoshare connects vehicle owners with people who need bikes and cars on rent. Owners earn from idle vehicles, and renters get flexible ride options.
Visit Motoshare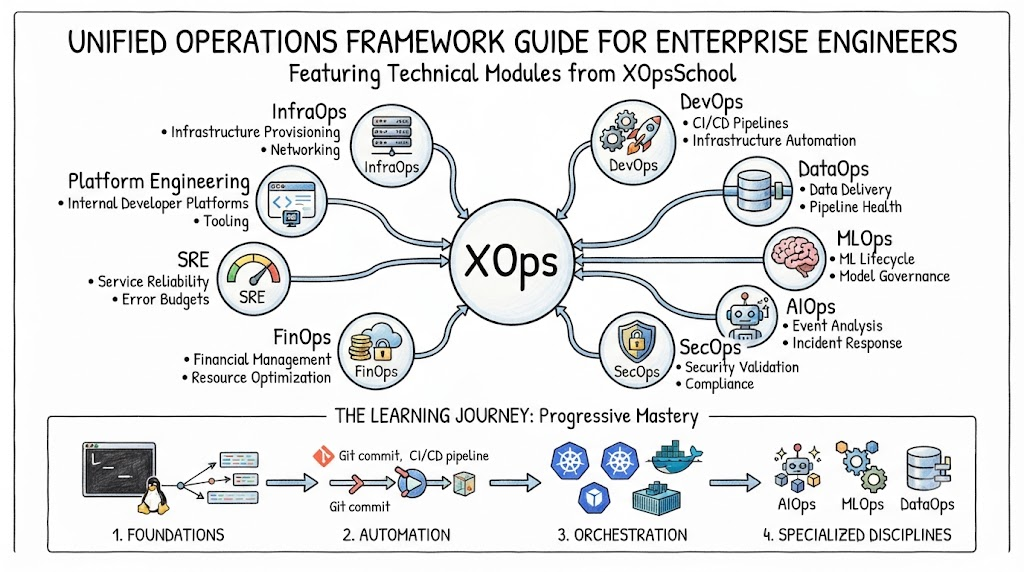
Introduction
Modern software engineering environments demand cohesive operational insight across diverse infrastructure, data, and machine learning stacks. While isolated teams previously maintained separate workflows, today’s distributed architectures require integrated practices that align deployment speed, platform resilience, and automated telemetry. This operational convergence defines the emerging practice known as XOps, serving as an umbrella approach that bridges continuous integration, cloud provisioning, data pipelines, and intelligent monitoring. For engineers and technology leaders evaluating modern curricula and practical tutorials, platforms like XOpsSchool illustrate how interconnected operational practices function in enterprise environments. By moving beyond isolated tooling and adopting cross-functional operational standards, organizations can streamline releases, eliminate delivery bottlenecks, improve overall platform reliability, and deliver resilient digital products across multi-cloud infrastructure.
What Is XOps?
XOps represents an umbrella framework where the variable “X” stands for any operational discipline, including DevOps, DataOps, MLOps, AIOps, SecOps, and FinOps. Rather than treating software deployment, data warehousing, model lifecycle management, and infrastructure monitoring as disconnected domains, this methodology unifies automation principles across the entire digital lifecycle. For instance, consider an enterprise recommendation engine: DevOps engineers deploy the core containerized microservices via continuous delivery pipelines; DataOps professionals validate and stream catalog data; MLOps engineers automate training, versioning, and inference serving; SecOps guards identity boundaries; FinOps manages dynamic compute costs; and SRE teams uphold stringent reliability budgets. Because every component relies on shared infrastructure, telemetry, and automated policies, XOps establishes standardized operational baselines that keep the entire business system reliable, secure, and maintainable.
What Does XOps Include?
The modern operational ecosystem unites multiple disciplines that previously operated within isolated technical siloes. Integrating these specializations ensures end-to-end observability, consistent governance, and automated continuous delivery across infrastructure layers.
| XOps Discipline | Primary Focus | Typical Responsibilities |
| DevOps | Software delivery and infrastructure automation | Managing CI/CD pipelines, container runtimes, version control, and rapid deployment automation. |
| DataOps | Continuous data delivery and pipeline health | Automating ETL/ELT workflows, enforcing data schemas, validating data quality, and monitoring pipeline latency. |
| MLOps | Machine learning lifecycle and model governance | Automating model deployment, tracking feature stores, monitoring data drift, and managing retraining loops. |
| AIOps | Intelligent event analysis and incident response | Correlating multi-source telemetry, running anomaly detection algorithms, and driving automated self-healing. |
| SecOps | Continuous security validation and compliance | Embedding static/dynamic vulnerability scans, secrets rotation, identity governance, and compliance testing. |
| FinOps | Cloud financial management and resource optimization | Tracking unit metrics, eliminating idle compute capacity, monitoring resource quotas, and optimizing cloud spend. |
| SRE | Service reliability and error budget management | Defining SLIs/SLOs, conducting blameless postmortems, managing incidents, and eliminating manual engineering toil. |
| InfraOps | Base infrastructure provisioning and networking | Managing compute clusters, multi-region routing, hypervisors, hardware abstraction, and physical or virtual networks. |
| Platform Engineering | Internal developer platforms and operational tooling | Providing curated self-service developer portals, building reusable deployment blueprints, and streamlining developer experience. |
What Is XOpsSchool?
XOpsSchool functions as a dedicated technical learning and knowledge platform designed to guide professionals through modern IT operations, automation pipelines, and multi-domain engineering disciplines. Through curated curriculum paths, engineers can explore continuous integration, cloud-native deployments, Kubernetes management, GitOps architectures, infrastructure as code, automated telemetry, and machine-learning operations. The resource emphasizes practical implementation over abstract theory, helping practitioners understand how modern enterprise tools intersect across real-world operational environments. By offering structured guides, tutorials, and practical architectures, the platform equips software developers, system administrators, and infrastructure engineers with the foundational and cross-domain knowledge needed to adapt to evolving cloud standards and modern operational frameworks.
Why Is XOps Important?
The rapid adoption of microservices, serverless compute, distributed databases, and artificial intelligence workloads has dramatically increased architectural complexity across enterprise environments. When operational teams manage monitoring, deployment, and security in disconnected toolsets, cross-team communication degrades, incident resolution times lengthen, and delivery velocity stalls. Unifying these areas under an operational umbrella establishes single-pane-of-glass observability, automated compliance checks, and clear cross-team ownership across all application components. By standardizing continuous integration patterns, infrastructure automation, and automated alerting across development, data, and machine learning initiatives, engineering teams successfully minimize downtime, reduce operational debt, and achieve sustainable release velocity across dynamic, distributed environments.
Why Choose XOps Training?
Pursuing comprehensive cross-operational education enables technology professionals to develop versatile engineering skill sets that bridge the gap between traditional operations and specialized disciplines. Engineers transitioning through structured learning acquire the technical breadth required to debug complex production issues, whether the root cause originates in a broken deployment script, an unvalidated database schema, or a drifting machine-learning feature pipeline. Expanding beyond isolated skill sets fosters greater collaboration between engineering teams, improves platform resilience, and accelerates problem-solving across production systems. Gaining this unified perspective equips developers, system administrators, and reliability engineers with the strategic and technical depth necessary to manage distributed cloud infrastructures effectively.
How Does XOps Training Work in Practice?
A practical, production-grade learning journey must emphasize progressive technical mastery through hands-on labs and realistic operational scenarios rather than passive video consumption. Engineers begin with Linux internals, shell scripting, and network packet analysis before advancing to Git workflows and continuous integration engines. From there, practitioners package microservices into immutable containers, orchestrate them with Kubernetes, and provision underlying cloud resources using declarative infrastructure-as-code patterns. Once fundamental deployment automation is established, learners integrate distributed tracing, automated vulnerability scanning, and error budget tracking. Advanced modules subsequently incorporate streaming data pipelines, model registry automation, and algorithmic log correlation, ensuring engineers gain practical experience debugging real system failures across diverse production-style environments.
XOps Certification: What Should You Look For?
When evaluating an industry certification, engineers should examine whether the curriculum prioritizes practical, hands-on lab evaluations over multiple-choice theoretical assessments. A rigorous program should test your ability to debug faulty Kubernetes manifests, restore failing continuous delivery pipelines, isolate infrastructure drift in Terraform configurations, and resolve data pipeline bottlenecks under realistic conditions. It must also incorporate comprehensive coverage of container runtimes, observability stacks, identity access policies, and automated alerting architectures across hybrid or cloud-native environments. While a credible credential effectively validates structured technical knowledge and disciplined study habits, engineers must remember that certifications complement—rather than replace—demonstrated hands-on debugging experience and real-world system architecture design.
XOps Tools: Understanding the Technology Stack
Modern cross-functional operations rely on specialized open-source frameworks and enterprise platforms that manage continuous delivery, automated infrastructure, application orchestration, and deep operational telemetry.
| Operational Area | Example Tools | Practical Purpose |
| Version Control & GitOps | Git, GitHub, GitLab, Argo CD | Managing source code repositories, tracking revision histories, and synchronizing cluster state declaratively. |
| Continuous Integration | Jenkins, GitHub Actions, GitLab CI | Automating code validation, running regression test suites, compiling assets, and generating container images. |
| Container Orchestration | Docker, Podman, Kubernetes, Helm | Packaging application dependencies into containers, scheduling cluster workloads, and managing scaling policies. |
| Infrastructure as Code | Terraform, OpenTofu, Ansible | Provisioning reproducible cloud resources, automating server configuration, and eliminating manual infrastructure drift. |
| Observability & Logging | Prometheus, Grafana, OpenTelemetry | Collecting cluster metrics, tracing distributed transaction paths, and assembling operational visualization dashboards. |
| Log Management | Elasticsearch, Logstash, Kibana, Splunk | Ingesting high-volume log streams, parsing operational logs, and querying application debug records during incidents. |
| Intelligent IT Operations | Dynatrace, Datadog, BigPanda | Correlating system anomalies, grouping duplicate alerts, and identifying root causes across distributed components. |
| Secrets & Security | HashiCorp Vault, Trivy, SonarQube | Scanning source code dependencies, enforcing least-privilege identity access, and rotating dynamic infrastructure secrets. |
DevOps Training as the Foundation of XOps
Proficiency in DevOps core concepts serves as the primary prerequisite for mastering advanced operational practices like DataOps, MLOps, and AIOps. Because all advanced data pipelines and machine learning models ultimately run on underlying cloud clusters, engineers must first master automated deployment pipelines, version control standards, and declarative infrastructure. Learning how to containerize workloads, manage stateful and stateless Kubernetes pods, implement blue-green rollout strategies, and configure automated health probes provides the technical scaffolding needed to support complex workloads. Once an engineer masters continuous integration, immutable infrastructure, and production telemetry, applying these automated delivery cycles to data warehouses and machine learning platforms becomes an intuitive extension of their existing engineering foundation.
AIOps Training: Adding Intelligence to Operations
Algorithmic IT operations integrate automated machine learning models with continuous telemetry ingestion pipelines to correlate events, detect anomalies, and filter noisy monitoring alarms. Instead of requiring on-call engineers to parse thousands of raw alerts during outages, intelligent monitoring platforms aggregate related incident signals, isolate probable root causes, and trigger automated remediation playbooks. However, implementing intelligent operational tooling requires an important practical caveat: algorithmic analysis is entirely dependent upon the quality, freshness, and completeness of the underlying telemetry data. Organizations that attempt to deploy machine-learning alerting mechanisms over fragmented logs, uncalibrated metrics, and broken tracing pipelines will simply amplify operational noise and generate misleading incident correlations.
MLOps Training: Taking Machine Learning Into Production
Machine learning operations adapt continuous integration and automated deployment patterns specifically to the lifecycle of predictive algorithms and generative models. While traditional software deployments focus primarily on executable binaries and static container configurations, machine learning systems introduce additional complexity because model behavior depends directly on dynamic input data distributions. Consequently, engineers in this domain must automate training pipelines, maintain versioned feature stores, package inference runtimes, and monitor production predictions for statistical accuracy degradation known as model drift. Connecting MLOps workflows with standard continuous deployment pipelines ensures that data scientists can deploy, validate, and retrain machine learning models reliably without creating manual operational overhead or platform downtime.
DataOps Training: Making Data Operations Reliable
Data operations bring software engineering discipline, continuous integration, and automated testing to data engineering, ETL workflows, and analytical platform operations. In modern enterprise architectures, analytics engines and real-time dashboards can fail silently when upstream database schemas change unexpectedly or records arrive corrupted. Implementing automated operational practices ensures that data pipelines incorporate schema validation gates, continuous data lineage tracking, transformation testing, and latency monitoring at every processing stage. For example, when an operational e-commerce database alters its billing schemas, an automated pipeline catches the discrepancy immediately, halts ingestion before downstream analytics are corrupted, and alerts data engineers, preserving analytical integrity across production dashboards.
Real-Life Scenarios and Operational Experiences
- An e-commerce platform experienced cascading weekend outages when a newly deployed recommendation model exhausted available cluster memory; cross-functional teams resolved the incident by establishing unified resource quotas, automated rollback checks, and integrated pod telemetry.
- A financial services enterprise reduced high alert volumes by eighty percent after deploying automated correlation engines across their logging infrastructure, enabling site reliability engineers to isolate failed database transactions within seconds.
- A healthcare analytics team prevented silent report corruption by implementing schema validation tests within their continuous data integration pipelines, immediately intercepting malformed hospital intake logs before reaching production data warehouses.
- A SaaS infrastructure team resolved continuous configuration drift across multi-region environments by transitioning from manual cloud configurations to declarative infrastructure-as-code templates managed through synchronized Git repositories.
Common Operational Pitfalls to Avoid in Distributed Environments
- Adopting complex deployment tools without first mastering foundational Linux systems, fundamental networking, and containerization principles.
- Treating security as an afterthought rather than embedding automated vulnerability scanning and secrets management directly within deployment pipelines.
- Relying exclusively on high-level dashboard metrics while neglecting distributed tracing and structured application logging across backend services.
- Attempting to implement artificial intelligence operations before establishing reliable monitoring telemetry and clean operational log pipelines.
- Building isolated, manual data workflows that lack automated regression testing, schema enforcement, and systematic data validation.
- Deploying machine learning models directly into production environments without automated feature versioning, drift tracking, and rollback configurations.
- Overlooking cloud financial tracking, leading to runaway compute expenditures and unmonitored idle infrastructure across development clusters.
- Creating internal operational silos where platform engineers, data teams, and developers use conflicting tools and disconnected communication channels.
How XOpsSchool Can Support the Learning Journey
Engineers seeking to expand their operational capabilities across diverse domains benefit from structured, vendor-neutral learning paths that emphasize practical implementation. Educational platforms like XOpsSchool provide technical tutorials, conceptual architecture breakdowns, and step-by-step guides covering core DevOps pipelines, Kubernetes administration, Terraform automation, and GitOps workflows. Furthermore, practitioners can explore specialized modules dedicated to reliability engineering, service-level management, automated observability, intelligent incident detection, and scalable data operations. By presenting complex infrastructure concepts through clear, practical frameworks, learners can bridge the gap between individual technical tools, master modern platform engineering principles, and build the multidisciplinary knowledge required to manage resilient, production-ready cloud environments.
How to Get the Most From an XOps Course
Maximizing the value of technical operational education requires an active, iterative learning cycle: Learn the foundational theory, Implement the infrastructure locally, intentionally Break the configuration, Troubleshoot the resulting error states, Document the diagnostic steps, Automate the remediation, and Measure the runtime performance. Rather than simply copying code snippets into terminal windows, engineers gain deep competence by simulating authentic production failures. Deploy a distributed application onto a local Kubernetes cluster, misconfigure its readiness probes, observe how traffic routing fails, inspect the system event logs, and repair the health checks. Practicing intentional fault injection, analyzing unexpected metric spikes, and automating system recovery transforms passive conceptual understanding into resilient engineering expertise.
Frequently Asked Questions
1. What is the fundamental difference between DevOps and XOps?
DevOps focuses primarily on automating the collaboration, continuous delivery, and infrastructure provisioning between software development and IT operations. In contrast, XOps serves as an umbrella paradigm that extends these automated delivery and reliability principles to specialized domains including data engineering, machine learning pipelines, platform security, and cloud cost management.
2. Can beginners start learning these operational methodologies without prior experience?
While beginners can grasp core concepts, successful practitioners should first master basic Linux command-line navigation, networking fundamentals, and version control using Git. Establishing this operational baseline ensures you understand system processes before attempting to manage distributed Kubernetes clusters, multi-stage delivery pipelines, and automated cloud infrastructure.
3. Which programming and scripting languages are most valuable across operations?
Python and Bash remain the most essential scripting languages for writing automation utilities, managing data pipelines, and interacting with cloud APIs. Additionally, gaining familiarity with Go is beneficial for platform engineers, as major cloud-native operational tools, including Docker and Kubernetes, are built using the language.
4. How does continuous testing integrate into automated data operations?
Data operations embeds automated verification scripts within ETL pipelines to test table schemas, check for null values, validate data types, and verify row counts. Catching malformed data early prevents downstream analytics dashboards, predictive machine learning models, and customer-facing reports from consuming unverified, corrupted information.
5. Why do modern IT operations require dedicated financial management practices?
Cloud-native architectures allow engineers to spin up elastic compute and storage resources instantly, which can lead to runaway infrastructure expenses if left unmonitored. Dedicated financial management integrates cost visibility, resource allocation tags, and automated shutdown policies directly into delivery pipelines, preventing unexpected budget overruns across teams.
6. What role does telemetry play in algorithmic incident correlation systems?
Algorithmic operations rely completely on structured metrics, logs, and distributed traces to identify abnormal system behavior and cluster related error messages. Without clean, standardized telemetry pipelines, automated monitoring engines cannot accurately differentiate between routine metric spikes and genuine production-impacting outages across distributed services.
7. How does platform engineering support continuous operational practices?
Platform engineering teams design and maintain internal developer platforms that package complex infrastructure, deployment pipelines, and observability tooling into self-service portals. This enables software developers to deploy, test, and monitor their applications independently without needing to manually configure low-level cloud resources or container manifests.
8. What is model drift and why does it require automated operational monitoring?
Model drift occurs when real-world production data changes over time, causing a machine learning model’s predictive accuracy to decline gradually. Automated operational monitoring tracks incoming feature distributions, evaluates prediction metrics against live outcomes, and automatically triggers retraining pipelines when statistical variations exceed established tolerance thresholds.
9. Are industry certifications mandatory for obtaining a platform engineering role?
Certifications are not strictly mandatory, but they provide structured learning paths and validate your theoretical understanding of complex cloud architectures. However, hiring managers prioritize demonstrable engineering ability, such as personal code repositories, hands-on lab projects, and practical troubleshooting experience over static multiple-choice testing credentials.
10. How does GitOps streamline production cluster deployments?
GitOps uses version-controlled Git repositories as the single source of truth for desired infrastructure and application states. Automated operators running inside the target clusters continuously compare the running system with the repository manifests, automatically applying updates or correcting unauthorized drift without requiring manual terminal access.
11. What is the primary difference between monitoring and observability?
Monitoring tracks predetermined system metrics, such as CPU utilization or HTTP error counts, to tell engineers whether a system is currently functioning. Observability infers the internal state of complex systems by analyzing external outputs like distributed traces and structured logs, allowing engineers to diagnose novel, unforeseen failure modes.
12. How does automated security scanning fit into continuous deployment?
Automated security practices integrate static code analysis, software bill of materials scanning, container vulnerability inspections, and compliance checks directly into early pipeline stages. This automated validation stops vulnerable dependencies from reaching production environments, ensuring security policies are enforced continuously without introducing manual operational delays.
Conclusion
Embracing cross-functional operational methodologies enables engineering organizations to overcome structural silos, manage modern cloud complexity, and build resilient digital platforms. By combining automated deployment workflows, rigorous data validation, intelligent incident response, and structured reliability engineering, teams achieve sustainable delivery speed while protecting application availability. Developing these versatile capabilities requires consistent, practical experimentation across Linux systems, container orchestrators, infrastructure automation tools, and continuous observability frameworks. Rather than treating software delivery, data engineering, and machine learning as disconnected operational domains, committing to multidisciplinary technical mastery ensures engineers and organizations can adapt to evolving industry standards, resolve production challenges efficiently, and maintain high-performing enterprise architectures.
