MOTOSHARE 🚗🏍️
Rent Bikes & Cars Directly from Owners
Motoshare connects vehicle owners with people who need bikes and cars on rent. Owners earn from idle vehicles, and renters get flexible ride options.
Visit Motoshare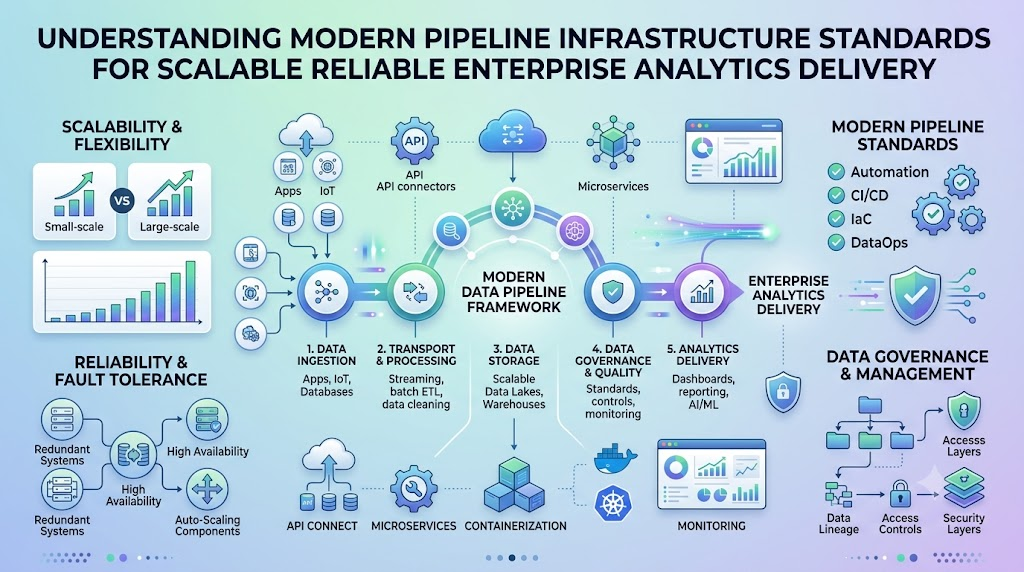
Introduction
Fast-growing businesses count on accurate figures to steer critical choices and stay ahead of competitors. Dirty inputs, calculation blunders, and stalled spreadsheets quickly mislead directors, triggering expensive mistakes across entire departments. Whenever a file job halts mid-flight, engineers squander daylight repairing broken tables by hand. This article unpacks automated data transfer, active validation gates, and early-warning monitoring tactics for technical groups. You will discover practical ways to eliminate bottlenecks, configure top utilities, and sharpen team operations. Students and practitioners explore TheDataOps.org to learn real-world engineering methods that eliminate everyday data friction.
What Is DataOps?
Imagine municipal pipes that deliver fresh drinking water into family homes across a busy city. If muddy soil leaks into a cracked fitting, nobody can safely drink from that faucet. DataOps functions like a dedicated crew of utility technicians for your corporate computer systems. It unites software authors, data analysts, and system administrators around common rules and rapid iterations. This collective relies on automated robots, swift checks, and clean schedules to transport uncorrupted information. Such close cooperation wipes out painful slowdowns, accelerates shipping speed, and keeps reporting tools running smoothly.
Why Does DataOps Matter?
Companies require immediate, trustworthy facts to adjust stock levels, bill shoppers, and assist clients. Yet processing lines grind to a halt whenever workers move massive tables without programmatic assistance. Unchecked errors surface, records arrive late, and silent system halts deliver misleading graphs to senior executives. When unnoticed errors slip into production warehouses, managers squander capital on misdirected outreach and bad forecasts. DataOps tackles these frustrations by running background tests throughout every stage of the pipeline. It shields staff from dull, repetitive clicking so engineers can craft valuable digital products instead.
What Is TheDataOps.org
TheDataOps.org serves as a clear educational hub for people seeking modern data engineering methods. It publishes straightforward tutorials, architecture roadmaps, and deep dives into cloud infrastructure and workflow bots. Beginners find step-by-step guidance on continuous testing, observability practices, and data governance standards. The platform also highlights proven techniques for teams to plan and maintain their production pipelines together. Its primary mission centers on making technical data practices friendly and accessible for everyone.
DataOps Training and DataOps Course
Taking structured DataOps Training shows you how to move information without facing messy data corruptions. Learners practice Agile sprints to release updates steadily alongside DevOps tactics for smooth server maintenance. You discover how to write checks that catch bad fields before executives open their morning dashboards. A complete DataOps Course walks through cloud infrastructure, release managers, automated checks, and health trackers. Hands-on coding exercises matter immensely because reading dry documentation never develops true engineering muscle. Many beginners turn to TheDataOps.org for clear roadmaps that turn classroom lessons into working projects.
Comparison Table
| DataOps Area | Main Goal | Example Activity |
| Data Pipeline | Transport records cleanly | Ingest raw shopping orders into cloud storage |
| Automation | Eliminate hands-on steps | Trigger jobs automatically after files arrive |
| Testing | Spot flaws instantly | Catch blank email rows before database insertion |
| Observability | Track digital health | Send emergency messages when processing times spike |
| Data Quality | Ensure total accuracy | Strip out repeated customer accounts instantly |
| Orchestration | Sequence operations | Trigger cleansing scripts before updating sales views |
DataOps Certification
Earning a DataOps Certification validates your command of modern pipeline design, automation, and testing. It signals to prospective employers that you can build safe, dependable workflows from scratch. However, passing an online exam never replaces actual engineering grit on the job. You must merge formal test preparation with raw coding practice across messy, imperfect datasets. Master Python basics first, build an automated pipeline, apply strict data tests, and then claim your credential.
Data Pipeline Automation
Data Pipeline Automation replaces manual button pushing with software bots that execute tasks around the clock. Manual transfers consume valuable hours and invite human typos during stressful product launches. A standard pipeline uses six clear actions: Collect, Clean, Test, Process, Store, and Monitor. For instance, a booking site gathers reservations overnight and cleans up odd text characters. Next, custom scripts verify credit records before sending the clean batch to central storage. CI/CD pipelines verify your logic continuously, so new commits never knock your business dashboards offline.
DataOps Tools
Engineering groups select specific DataOps Tools because individual apps tackle distinct processing tasks. Python enables engineers to transform complex rows and reformat messy values with minimal code. Apache Airflow schedules tasks in exact order like an experienced train dispatcher. Apache Kafka streams live events between decoupled platforms without misplacing a single detail. Apache Spark processes huge datasets across clustered servers in seconds rather than days. Hadoop handles bulk file archives, and Kubernetes runs lightweight containers steadily in cloud regions. Jenkins runs regression tests on every commit, Grafana plots system uptime on visual displays, and Tableau generates easy executive charts. Since no organization uses every product, choose software that tackles your current team friction.
DataOps Platform
A unified DataOps Platform merges disconnected pipelines, storage buckets, and jobs into one command screen. It handles data ingestion, heavy compute stages, logic tests, job orchestration, system health, and data rules. Engineers no longer switch between multiple web tabs just to verify nightly batch runs. Before buying a subscription, evaluate integration hooks, total expenses, security boundaries, and performance limits. A capable platform must bind smoothly to your current databases without forcing teams into painful rebuilds.
Data Observability
Data Observability gives engineering squads sharp insight into every stage of their data pipelines. It continuously monitors pipeline speeds, file arrivals, missing records, job crashes, and unexpected batch sizes. For instance, if an e-commerce platform processes ten thousand records daily but sees ten today, alarms sound right away. Direct notifications ping support staff instantly so specialists resolve glitches before company leaders view broken dashboards. This constant surveillance prevents chaotic troubleshooting drills across tangled server logs.
Data Quality Management
Data Quality Management guarantees that enterprise numbers stay reliable, compliant, and ready for analysis. It catches blank fields, invalid phone structures, duplicate users, and broken computational logic. When unchecked errors contaminate storage layers, finance departments calculate flawed projections that harm investments. Automated safety gates validate incoming records instantly and drop malformed inputs before they touch your core warehouse. Trustworthy data inputs empower staff to make bold commercial moves with absolute certainty.
DataOps Consulting
Firms engage DataOps Consulting partners when broken pipelines disrupt operations and frustrate executive leaders. External consultants evaluate fragile architectures, slow transformation batches, manual workarounds, and missing alerts. They examine tool usage patterns to uncover simple ways to replace boring steps with smart bots. Capable consultants focus on resolving practical operational snags rather than selling expensive, unnecessary software licenses. These focused changes help in-house developers ship clean data assets without fear or delay.
Real-Life Scenarios / Experiences
- Logistics managers cut three hours of manual inventory validation each morning by installing automated data quality scripts that run right after dawn.
- Regional clinics eliminated treatment delays after setting up automated alerts that ping technicians whenever patient records fail to load overnight.
- Financial underwriters stopped incorrect credit grants by adding schema validation steps that drop malformed records before the approval engine starts.
- Video platforms avoided subscriber churn over holiday weekends by monitoring stream log volumes with automated observability dashboards.
DataOps Engineer Career Path
A DataOps Engineer constructs the automated railways that carry enterprise information securely between systems. To enter this high-demand field, master Python syntax, SQL commands, Linux shells, and Git versioning tools. Then, study modern data pipelines, automated testing libraries, cloud foundations, and workflow runners like Airflow. Create personal demonstration projects, such as a bot that gathers open transit numbers, inspects them, and emails a daily report. Practical projects on GitHub demonstrate your technical resourcefulness better than any buzzword-heavy resume.
Common Mistakes to Avoid When Choosing Data Operations Strategies
- Purchasing complex commercial software suites before mapping pipeline stages and clearing up basic process bottlenecks.
- Skipping unit and integration tests, which guarantees that faulty figures will break reporting tables later.
- Permitting operators to transfer sensitive production archives manually instead of writing auditable, automated migration scripts.
- Silencing monitoring notifications until angry department directors report empty spreadsheets during board meetings.
- Isolating data engineers from backend software teams, which sparks integration bugs whenever schema structures change.
- Adopting dozens of complex open-source frameworks at once when simple scripts deliver identical operational value.
- Neglecting centralized metric definitions, which causes team leads to argue over contradictory sales numbers.
- Exposing plain customer identifiers in staging sandboxes, which triggers severe regulatory penalties and safety breaches.
How TheDataOps.org Can Help
Educational resources on TheDataOps.org guide aspiring engineers and seasoned practitioners through practical data operations challenges. The platform features clear articles on pipeline architecture, automated validation, and core DataOps Engineer responsibilities. Readers learn how to evaluate modern tools, configure cloud resources, and introduce strict testing without wading through corporate buzzwords. It supports candidates pursuing industry credentials by highlighting real-world engineering drills and clean coding habits. These clear materials equip developers to eliminate delivery bottlenecks and maintain resilient data environments.
DataOps Tools
| Tool | Main Use | Simple Example |
| Python | Data coding | Clean up date formats in messy files |
| Airflow | Job scheduling | Run nightly database jobs in proper order |
| Kafka | Data streaming | Move live customer click events instantly |
| Spark | Data processing | Group millions of payment rows in minutes |
| Jenkins | Automation | Run tests on pipeline code before release |
| Grafana | Monitoring | Display colorful graphs of server health |
Frequently Asked Questions
1. What does DataOps mean in simple words?
DataOps describes a modern engineering method that uses smart automation to deliver clean data quickly. It unites data creators, software developers, and platform operators through common tools and automated practices. By using continuous testing routines, teams prevent system errors before reports reach decision makers.
2. Is DataOps just DevOps for data?
DevOps principles like continuous integration, automated deployment, and agile teamwork form the backbone of DataOps. However, DataOps also manages unpredictable data sources, changing schema designs, and sensitive personal records. It treats enterprise data as a living product that requires ongoing automated testing.
3. Do I need to know how to code to work in DataOps?
Solid scripting skills enable you to automate mundane jobs and cleanse raw inputs efficiently. Picking up Python and SQL gives you plenty of leverage to build checks, query tables, and bridge systems. You do not need deep algorithm knowledge, but daily scripting remains essential.
4. What is the difference between a Data Engineer and a DataOps Engineer?
Data engineers assemble the analytical pipelines and transformation models that shape company data. A DataOps engineer designs the surrounding delivery factory, including test runners, deployment scripts, and telemetry monitors. Both professionals collaborate closely to keep corporate data flowing without manual interference.
5. Why do automated data tests matter so much?
Automated tests inspect incoming records for empty values, incorrect formats, and weird outliers. If bad entries appear, the test halts the run before faulty inputs contaminate company dashboards. This immediate protection prevents executives from setting business strategy on misleading statistics.
6. Can small teams use DataOps methods?
Small departments gain huge advantages because smart automation eliminates repetitive daily maintenance chores. Basic setups using Python routines, Git branches, and a handful of automated checks save significant time. You never need expensive commercial platforms to establish stable, error-free pipelines.
7. What is data observability?
Data observability provides continuous visibility into the internal state and movement of enterprise data. It tracks delayed deliveries, missing values, broken runs, and memory exhaustion across the infrastructure. When problems arise, smart alert managers notify operators so technicians resolve issues immediately.
8. How long does it take to learn DataOps basics?
Dedicated students can understand core pipeline patterns and validation fundamentals within eight to twelve weeks. Focus your efforts on writing Python scripts, executing SQL transformations, and scheduling basic workflows in Airflow. Building functional portfolio projects accelerates learning and instills genuine technical confidence.
9. Which tool should I learn first as a beginner?
Begin your study with Python because its intuitive syntax supports virtually every data automation task. Next, pick up SQL to extract database rows and Git to track source revisions cleanly. These three foundational tools support nearly all modern enterprise data operations.
10. Does a DataOps certification guarantee a job?
A credential strengthens your job application by proving your dedication to modern delivery practices. However, hiring managers prioritize practical problem-solving skills over paper qualifications alone. Always reinforce your certification studies with open-source portfolio repositories that you built and tested yourself.
11. What causes most pipeline failures in production?
Unannounced format changes from external data sources cause the vast majority of pipeline crashes. A third-party provider might rename fields, alter timestamp formats, or provide completely blank inputs unexpectedly. Automated schema checkers trap these variations early so production databases stay intact.
12. How does TheDataOps.org help learners?
TheDataOps.org delivers practical lessons, career roadmaps, and tool summaries for engineers at every experience level. It translates intricate concepts like pipeline orchestration, automated testing, and observability into plain language. Readers gain practical skills to design, automate, and safeguard reliable data pipelines.
Conclusion
Healthy corporate analytics demand automated processing flows, round-the-clock monitoring, and strict data quality controls from start to finish. Mastering essential technologies like Python, Airflow, and Kafka empowers developers to replace fragile manual workflows with dependable code. Pursuing targeted credentials alongside practical coding labs prepares you for an impactful role as a DataOps engineer. Educational articles on TheDataOps.org provide clear guidance as you adopt modern engineering habits and refine your skills. Start by creating simple validation routines, test every incoming file, and produce data assets that colleagues can trust completely.
