MOTOSHARE 🚗🏍️
Rent Bikes & Cars Directly from Owners
Motoshare connects vehicle owners with people who need bikes and cars on rent. Owners earn from idle vehicles, and renters get flexible ride options.
Visit Motoshare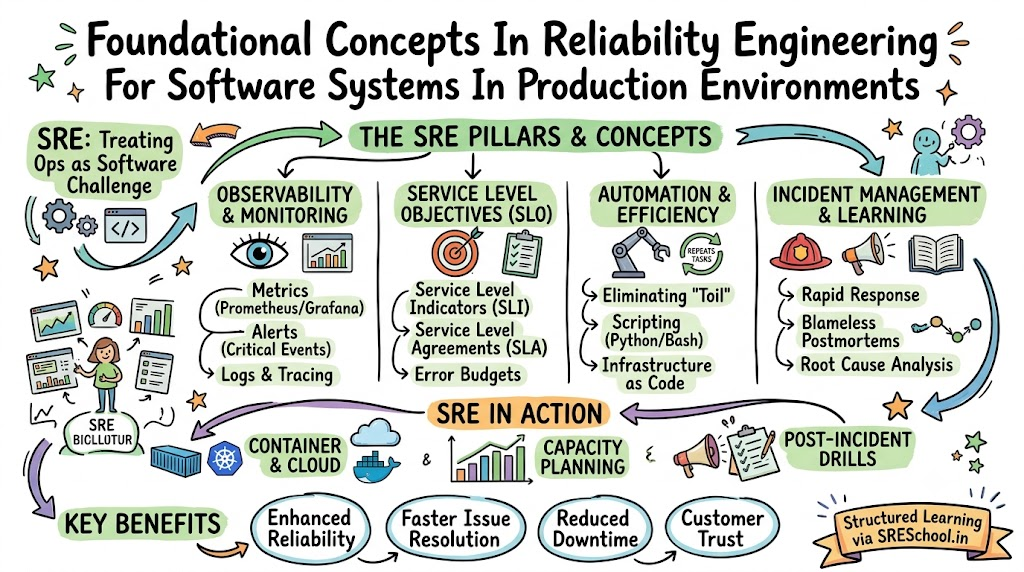
Introduction
Modern life runs on web platforms every single second of the day. Online banking, classroom portals, and ride apps must stay fast and healthy. Unexpected system crashes upset people and destroy trust in technology companies very quickly. Site Reliability Engineering combines clear computer programming with daily system care to stop outages. Teams write simple code scripts to mend broken internet servers before users notice. In this detailed guide, you discover how modern platforms stay fast, steady, and secure. You also explore everyday engineering duties, popular technical tools, and wise operational habits. SRESchool.in provides a welcoming learning space for anyone who wants to explore these foundational concepts. Students discover structured learning pathways that explain how modern digital operations truly work.
What Is Site Reliability Engineering?
Site Reliability Engineering treats everyday computer operations as a software challenge. Its primary purpose centers on keeping internet platforms healthy, rapid, and available. Reliability simply means an application opens cleanly and performs tasks without strange errors. High system uptime means a digital platform stays awake through the night. Strong performance ensures web pages load rapidly so visitors never wait in frustration. Good stability means servers handle massive waves of web visitors without shaking. Engineers write small automation programs to eliminate boring manual tasks from daily work. Digital monitoring tools inspect computer memory and network speed like sharp virtual eyes. Because of these smart steps, the whole platform runs smoothly and safely.
Why Does SRE Matter?
Every user expects an online store or mobile app to respond instantly. Sudden downtime breaks the customer journey and halts important digital payments cold. Sluggish applications frustrate visitors and push them toward competitor websites within moments. Severe service outages block vital communications and prevent people from getting work done. These failures damage customer trust and cost technology companies huge amounts of money. People naturally return to digital platforms that deliver fast results every single day. Teams need early warning signals before customers feel the sting of broken software. SRE gives engineers the right techniques to spot small glitches early. So, teams build strong digital guardrails that block repeat failures forever.
What Does an SRE Engineer Do?
A dedicated SRE Engineer protects active web services from sudden operational crashes. These professionals review live monitoring dashboards to track server memory and visitor traffic. They inspect urgent warning messages to identify faulty software before outages spread widely. When an incident appears, they coordinate quick repairs to restore regular service immediately. An incident means any sudden dip in system speed, quality, or stability. Next, engineers automate repetitive server tasks so machines resolve routine errors on their own. They direct capacity planning by reserving adequate cloud space before busy holiday seasons arrive. They configure remote servers housed inside safe data centers across the globe. They also collaborate with software developers to launch new features safely. Later, they analyze past failures to discover why the computer system broke.
What Is SRE Training?
Comprehensive Site Reliability Engineering Training gives ambitious students practical operational skills from scratch. Students begin with Linux basics to master command-line controls on remote computer servers. They study monitoring methods to track server health through clear visual graphs. Next comes observability, which reveals the internal health of complex software systems. Students examine Service Level Indicators to collect accurate performance data from real users. They establish Service Level Objectives as clear target benchmarks for daily service quality. They also review Service Level Agreements, which define legal commitments made to enterprise clients. Furthermore, students track error budgets to set safe boundaries for occasional system downtime. They practice incident response, cloud computing, Docker containers, and Kubernetes cluster management tools.
Why Consider SRE Certification?
A recognized Site Reliability Engineering Certification validates your knowledge of core reliability principles. Earning a certificate means passing an exam that tests fundamental system concepts. It gives beginners a clear roadmap that keeps study time productive and focused. It also links separate technical topics into an orderly, step-by-step learning path. Even so, holding a paper certificate alone never transforms you into a seasoned expert. Practical experience carries far more weight when a live database runs out of disk space. New learners should build small practice projects on their own home computers. Combining certified study programs with genuine lab experiments builds capable and confident engineers.
What Should an SRE Course Include?
A balanced SRE Course guides ambitious learners through ten organized learning milestones. Students master elementary vocabulary before touching live production cloud servers.
| Course Stage | Primary Skill Learned | Real-World Application |
| Basics & Linux | Terminal commands | Navigating remote computer servers |
| Observability | Metrics and alerts | Finding memory spikes early |
| Automation | Script writing | Restarting crashed software services |
| Cloud Defense | Kubernetes tools | Balancing user traffic spikes |
- Beginner SRE concepts: Learn basic definitions, core reliability goals, and elementary operational language.
- Linux and system basics: Navigate remote file directories, edit files, and run basic terminal scripts.
- Monitoring and alerts: Design visual metric dashboards and configure reasonable notification thresholds for servers.
- SLI and SLO concepts: Establish error budgets and record accurate latency numbers from user requests.
- Incident management: Coordinate fast team messages and troubleshoot issues calmly during active outages.
- Cloud and containers: Package independent applications inside lightweight container units using standard tools.
- Automation: Write short scripts to eliminate manual server restarts and repetitive daily cleanup work.
- Infrastructure management: Set up virtual cloud networks automatically by writing clear configuration files.
- Reliability projects: Build and maintain small live applications on real public internet infrastructure.
- Production practice: Repair simulated server crashes safely inside protected educational sandbox environments.
SRE Training in India
Technology enterprises across India continue adopting modern cloud systems at a breathtaking speed. Fast-growing companies build complex web applications that serve millions of active mobile users. Because of this massive expansion, tech firms hire DevOps professionals and reliability specialists continuously. Indian engineers frequently collaborate within distributed teams alongside partners around the globe. They oversee complex cloud infrastructure, write clean automation scripts, and protect production systems. Hands-on operational knowledge gives local job seekers a sharp advantage during technical hiring interviews. Engineers want practical training to handle massive user spikes during major shopping festivals. SRESchool.in offers an accessible starting point to help professionals build these high-demand skills.
SRE Tools
Engineers deploy specialized SRE Tools to track, repair, and scale distributed internet applications. Every tool fills a specific operational role within modern technology environments.
| Tool Area | What It Does | Example Use |
| Monitoring | Tracks system health | Check server errors |
| Logging | Records system events | Find hidden software faults |
| Tracing | Tracks user requests | Find slow internal services |
| Alerting | Sends urgent warnings | Detect big active incidents |
| Infrastructure | Manages system resources | Create cloud systems with Terraform |
| Containers | Runs small applications | Package services inside Kubernetes |
Prometheus gathers real-time metric data, while Grafana displays clear charts with bright color codes. Terraform builds complete cloud environments using standard text configuration files. Kubernetes organizes software containers so applications survive heavy web traffic without crashing down.
SRE Best Practices
Engineering groups follow proven SRE Best Practices to prevent catastrophic production failures. They establish crystal-clear service goals so developers understand exact performance boundaries. They track only critical data points to keep operational dashboards clean and readable. They adjust alarm thresholds carefully to remove useless notification noise for good. Engineers script repetitive daily tasks so computers perform maintenance without human help. They test every software update inside isolated testing environments before showing changes to users. Teams prepare detailed incident plans so everyone understands their role during an emergency. They hold post-incident meetings to study mistakes without pointing fingers at any single person. In addition, they clear out technical debt and forecast future computing capacity accurately.
Real-Life Scenarios
- Memory leak defense: A popular retail website slowed to a crawl during an afternoon flash sale. The monitoring chart revealed server memory climbing steadily until the program failed completely. An engineer on call caught the problem on Grafana within five minutes. The team activated an automated rule that restarted overloaded containers immediately without dropping customer carts.
- Massive game release: A new online game attracted four times more players than creators expected. The primary login server approached full computing capacity within fifteen minutes. Kubernetes detected the sharp traffic spike and launched six extra server pods automatically. The game stayed online, and eager players enjoyed their matches without experiencing annoying interruptions.
- Catching faulty database code: A programmer wrote a new update that accidentally slowed down search lookups. The automated testing pipeline flagged the high response time before customers experienced any delays. The team paused the deployment, rewrote the slow database query, and kept the service running fast.
Common SRE Mistakes to Avoid
- Flooding communication channels with alerts: Too many minor alerts create severe fatigue for on-call engineers. Set warning alarms only for critical emergencies that require fast human intervention.
- Ignoring empty error budgets: Shipping experimental features after burning through error budgets causes deep outages. Freeze high-risk code updates until your team restores baseline system stability.
- Hiding incident postmortems: Concealing operational mistakes guarantees that teams repeat the exact same errors later. Draft honest post-incident reviews to identify root architectural weaknesses clearly.
- Relying on manual server repairs: Fixing server errors by hand wastes valuable time during stressful emergencies. Write reusable automation scripts that repair common server glitches automatically every single time.
- Measuring uptime alone: A server can stay online while completely failing to return user account details. Track real response times and customer transaction success rates instead of simple server uptime.
- Blaming teammates for system accidents: Shouting at coworkers forces engineers to hide broken code from the team. Create an open culture that concentrates on fixing fragile software systems.
- Skipping disaster recovery drills: Untested recovery runbooks fail when a true production emergency strikes your servers. Run regular practice drills so your entire engineering team remains calm and prepared.
- Neglecting architectural runbooks: Incomplete operational notes confuse new team members during late-night support rotations. Write short, clear guides explaining how to restart every essential software service.
How SRESchool.in Can Support SRE Learning
SRESchool.in operates as an informative learning platform for students seeking practical systems reliability knowledge. The site provides Site Reliability Engineering Training to help beginners build practical operational skills. Learners can prepare for Site Reliability Engineering Certification through well-organized learning modules. Each structured SRE Course presents foundational ideas before moving into advanced cloud operational topics. Newcomers can study an accessible SRE Tutorial to grasp server architecture concepts quickly. The curriculum introduces essential SRE Tools that modern engineering groups use on the job every day. Students explore field-tested SRE Best Practices for running scalable internet applications without interruptions. Anyone working toward becoming an SRE Engineer can strengthen their operational engineering abilities. The platform also assists engineers seeking structured SRE Training in India.
SRE Learning Roadmap
This simple five-step roadmap guides you from basic ideas to hands-on production engineering.
Learn → Practice → Build → Test → Improve
- Learn: Master fundamental definitions, review basic Linux commands, and explore network communication protocols.
- Practice: Run local Docker containers, configure Prometheus monitors, and read live error logs carefully.
- Build: Deploy an interactive website across multiple cloud servers using clean automation scripts.
- Test: Disconnect application components intentionally to observe how your automated alerts respond.
- Improve: Refine your warning thresholds, eliminate slow code routines, and automate every remaining manual chore.
Frequently Asked Questions
1. Does a complete beginner need deep programming experience?
Newcomers only need simple scripting skills to begin exploring this operational field. You never need to build large enterprise applications like full-stack software developers do. Writing small Python or Bash scripts helps you automate basic system tasks easily. That modest foundation provides enough coding ability to start your technical journey with confidence.
2. How does reliability engineering differ from general DevOps?
DevOps describes a wide cultural philosophy that encourages teamwork between programmers and operations staff. Reliability engineering offers concrete software practices to implement that cooperative philosophy effectively. Developers write exciting user features, while reliability engineers use code to keep systems online. Both groups share the same goal of releasing stable software quickly.
3. What does an error budget mean in plain words?
An error budget represents the acceptable amount of downtime an internet application can experience. Every online service encounters small hiccups and brief server delays throughout the year. If your team preserves its budget, you can deploy creative features with confidence. If errors exhaust that budget, you must direct all effort toward fixing stability issues.
4. Why does modern cloud administration depend on Linux?
Most internet cloud servers run on Linux distributions rather than everyday consumer operating systems. Engineers use command-line terminals to inspect server memory, file directories, and network connections. Running quick terminal commands allows you to troubleshoot issues rapidly during surprise system outages. Linux serves as the foundational operating system for nearly all cloud engineering tasks.
5. What does the term observability mean to a beginner?
Observability means judging the internal health of a software system using external clues. Engineers inspect performance metrics, event logs, and network traces to uncover hidden problems. This clear diagnostic data helps teams identify bugs without guessing in the dark. It gives your entire team deep visibility into running cloud applications.
6. Can an experienced system administrator transition into this specialty?
System administrators already understand operating systems, computer networking, and server hardware very well. They can pivot into reliability roles by learning modern scripting, container tools, and cloud platforms. Practicing modern automation helps system administrators step into software-driven operations with genuine confidence.
7. What makes system alerts practical instead of noisy?
A good alert fires only when real visitors experience serious trouble on your website. Noisy alerts send endless warnings for tiny hiccups that resolve themselves without human help. Experienced teams tune alarm systems so pagers wake engineers only for critical incidents. This healthy discipline prevents dangerous alert fatigue across the engineering team.
8. What happens during a blameless post-incident review?
A blameless review gathers the team to discuss an outage without accusing individual workers. Everyone assumes teammates made the best possible choices with the information they had that day. The real goal centers on finding weak processes and fixing fragile code so failures never return.
9. Why do modern companies package software inside containers?
Containers bundle an entire software application alongside all the supporting files it requires. This clean packaging ensures that the application runs identically on any computer server. Containers allow engineers to test, deploy, and scale application components quickly whenever web traffic climbs high.
10. Does daily operational work demand advanced mathematics?
Daily operational engineering duties never require advanced calculus, linear algebra, or complex geometry. You only need simple arithmetic to calculate uptime percentages, server latency, and error budgets. Basic math helps you read performance graphs and set sensible availability goals for web platforms.
11. What is the core difference between an SLI and an SLO?
A Service Level Indicator measures the actual real-time speed and performance of your system. A Service Level Objective represents the formal target percentage your engineering team aims to hit. For example, your target objective might sit at ninety-nine percent, while your live measurement shows ninety-nine point four percent.
12. How much time does a beginner need to learn these skills?
Dedicated students can master fundamental operational concepts within six months of steady daily practice. Focus your energy on Linux basics, cloud environments, simple scripting languages, and system monitoring tools. Building small hands-on projects will help you understand these core concepts much faster than reading theory alone.
Conclusion
Dependable internet networks keep our connected society moving forward smoothly every single day. Site Reliability Engineering blends smart software automation, watchful monitoring, and clear service targets to protect user trust. Beginners can start by mastering the Linux command line, exploring container tools, and practicing incident response steps. SRESchool.in provides a clear educational environment where learners can explore system reliability concepts through structured guidance. When engineering teams replace dull manual labor with automation and examine mistakes openly, web platforms become resilient. Creating real hands-on projects will sharpen your operational understanding and prepare you for rewarding careers in modern technology.
